Out of stock ECS component
Overview
This repository contains a tasks which will be running a Lambdas.Product processor lambda will get the products events from the queue as soon as it’ll arrive. For the new product(s), the lambda will call the product service to load the product details. For the new product(s), lambda will call the OSP availability override API to get all the overrides against the product for all the stores. The lambda will insert/update the data for products, product caps and dual masking. For dual masking , the records will go to priority 2 SQS for further processing.OSP order checkout, Edit cancellation webhook will be triggered and hit product availability endpoint and pass order Id. Order Id will be passed to order processing SQS. 1. New order ids will go to New SQS 2. Edit order Ids will go to Edit SQS 3. Cancelled order Ids will go to Cancelled SQS
Aui to Big Query Component
Overview
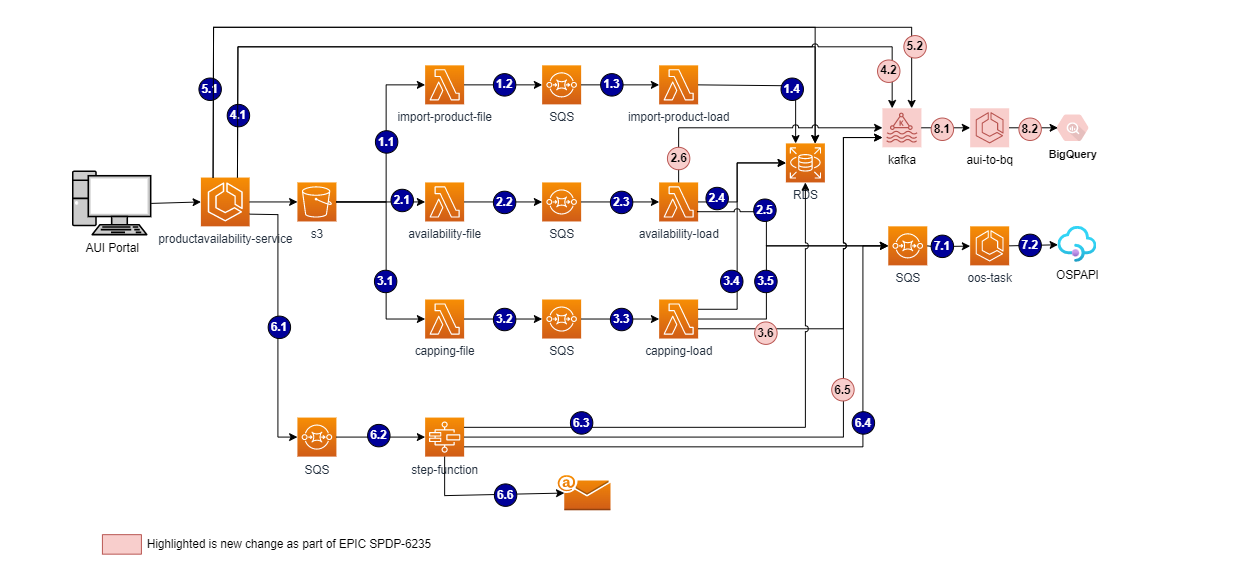
This component is use to fetch records from the processor and service of AUI and put it into Big Query Table. working of the component is divided into two parts , 1. Processor/Service to kafka 2. From Kafka to Big Query to run this component we required Big Query dataset, 1 ECS task to Run this component Continuously,and for kafka setup we require kafka configuration
Processor/Service to kafka:
working of Availability user Interface (AUI) is to get us the masking and capping details as per our requirement, this part of the component will sen our that record to the kafka which fetch that record in particular time interval
Kafka to Big Query :
we are getting our data from kafka in bunch so in this component we segregate that records in to parts Capping and Masking once we get that separation, our component will send that record in respective table in Big Query
Accounts Needed
AWS accounts will be required for DEV/SIT/PROD. Google Cloud platform for Big Query
References
Python Service with infrastructure as code.
Unit tests & code coverage at about 90%+
Configuration for multiple environments, DEV/SIT/PRD
Document |
Ref |
|---|---|
Architecture Document |
|
Jira Story |
|
Bitbucket repository |
Testing Approach
We will be using a BDD approach where the behaviour will be tested first the code will be developed to match the tested behaviour.
Deployment strategy
The deployment is handled by a jenkins multibranch pipeline, https://jenkins.p.morconnect.com/sonarqube/dashboard?id=aui-osp-productavailability-oos-task-feature. The commit in the develop branch will automatically deploy the application to the aws environments. The release is done by standard process of tagging the release branch, and by building and deploying from the tags. The tag format is sit-v*-<commit> for nonprod and prd-v*-<commit> for the production release. These tags are manually built on jenkins after the change request has been approved. The release branch is merged to the stable master branch after the successful production deployment.
Backout
To back out we will build off the last release in the master branch and redeploy an old tag version, this shall take around 5 minutes. This will minimise the data loss in case a problem is discovered.
Diagrams
Product Import Processor Gives the overview from the product import processor which contains file processor and load processor
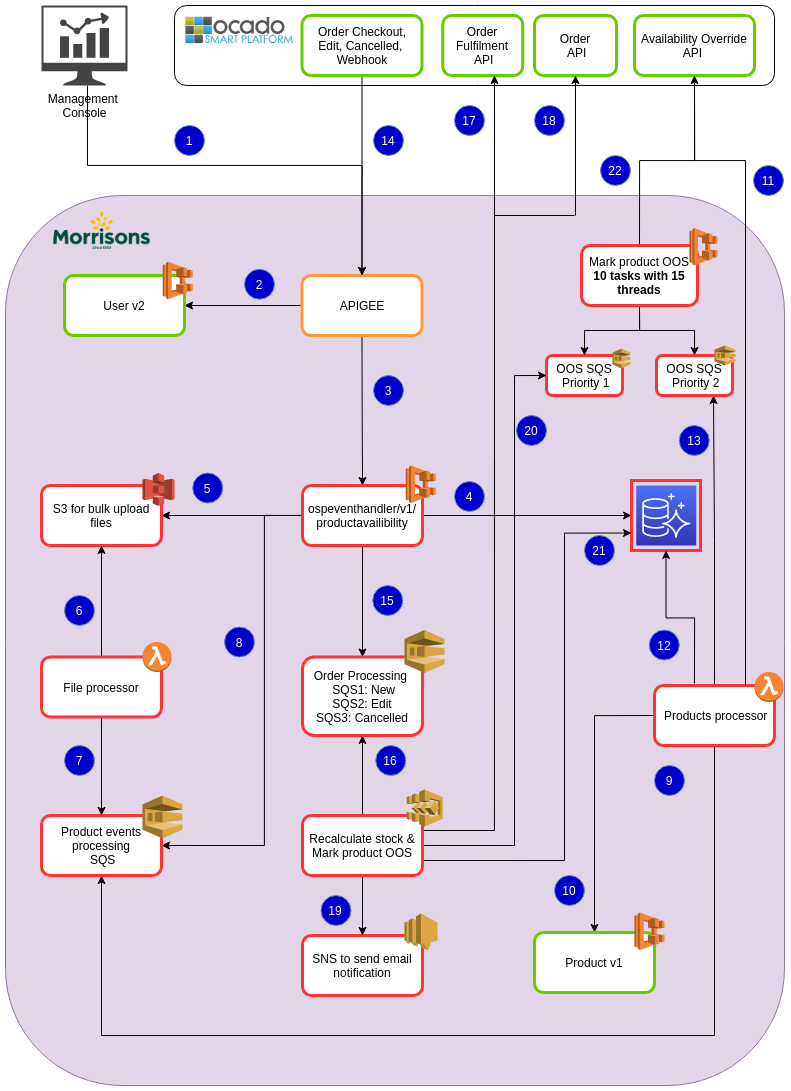
Aui To Big Query Component it gives the representation of the component